Same Game. Different AIs. Best Feel Cost About $1.65
I tried the same study reward idea with different AIs, and the build with the best feel cost about $1.65.
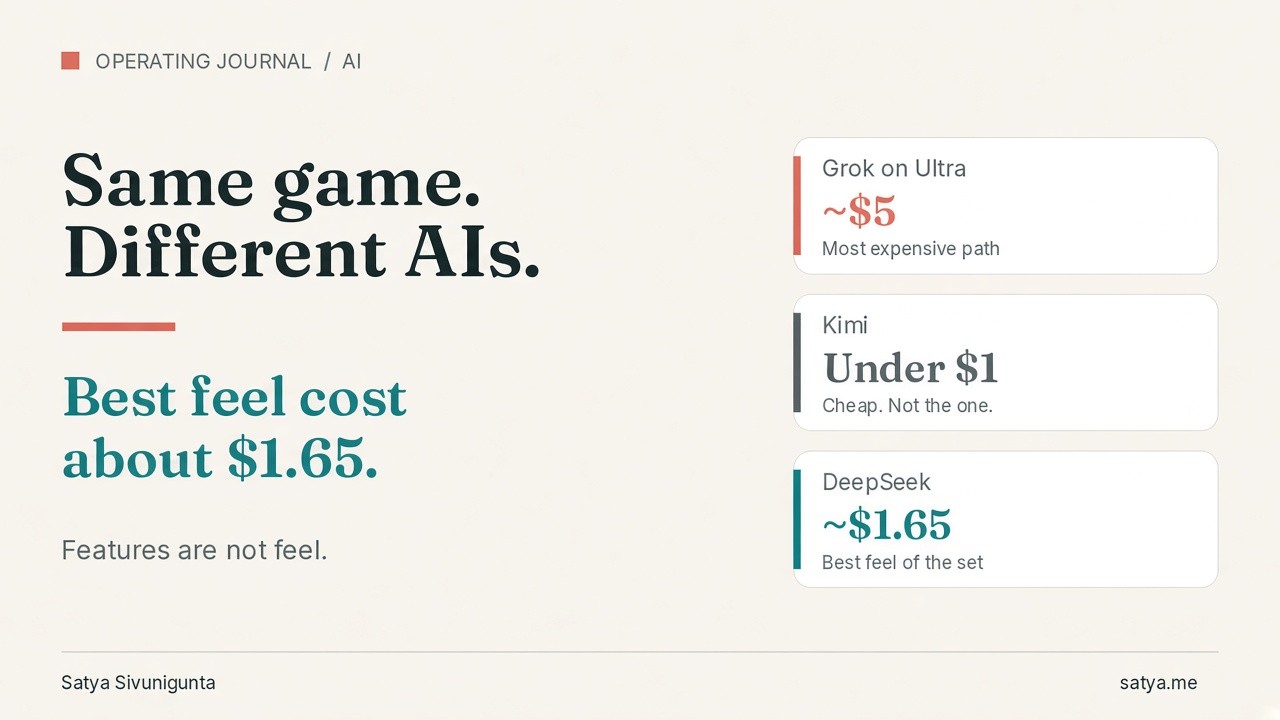
The last build felt the best. It was DeepSeek. It cost about a dollar sixty-five.
I keep that sentence on purpose. The easy story is "AI games are free now." The real story is messier, cheaper than people fear, and more about feel than features.
What I was building
A study reward: answer questions, earn game minutes. One-button pixel cube runner. Geometry Dash energy. If the reward feels bad, the loop fails. So I tried more than one builder.
Grok on Ultra: about $5
About 2 to 3% of a $200 Ultra plan. Call it about five dollars. Most expensive path. Not the best feel. A bigger bill does not buy better juice. Feel is separate.
Grok path feel stand-in from an early build. Not the final Grok cut. No gameplay audio in this clip.
Kimi: under a dollar
Pretty city. Working goal. Coins. Portals. Then: only two levels, short crash, stuck timer. Under a dollar. Cheap is not enough if the loop breaks. One failed call: 16,000 output tokens, almost all reasoning, zero usable code. Thinking hard is not shipping.
Kimi build. No gameplay audio in this clip.
DeepSeek: about $1.65
Beat synced levels. Parallax. Particles. Real HUD. I said holy cow. Later pass: six worlds, ship flying, gravity flips, cloud boss, soundtrack in code. About $1.65. Best feel of the set.
DeepSeek mid build. Procedural audio kept.
DeepSeek later pass. Soundtrack in code kept.
What humans still did
Glue work. Testing. Demo renders. Phone fixes. AI built most of it. People finished it. I am not selling magic. I am reporting a build.
Bills I will stand behind
Grok ~$5 · Kimi under $1 · DeepSeek ~$1.65
Caveats
Not a lab test. Prompts differed. Later builds learned from earlier ones. Read it as: for this brief, on this day, DeepSeek won on feel at about $1.65.
How I would run it again
Tiny brief. More than one model. Judge only: first three seconds, phone survival, what I actually spent. Play does not lie.
Final cut
Same brief. Four builds. One cut.
Final cut, about 106 seconds. Grok and Kimi sections are silent. DeepSeek keeps its procedural audio.
Takeaway
Features are not feel. Cheap ≠ good. Expensive ≠ good. Winner was middle on money, top on feel. Model choice is which one ships after the glue work.
Close
Which model would you trust with your next build?
Work with me
An operator's honest read for founders, owners, and CEOs. One sharp session, a full diagnosis, or a fractional seat.